
Models under your control
Text and vision GGUF with upload, download and profiles managed from the node itself.
Xeretron AI Server · Your private AI, in your own environment
NO tokens · NO limits · ALL yours
Xeretron installs models, voice, documents, APIs and AI operations wherever you decide: your computer, your server, or your company's. Your data stays under your control — whether for personal use, a small team, or an entire organization.
The paradigm shift
Modern AI is sold as a cloud token counter. Xeretron proposes another relationship: your private AI running in your own environment, far from being a distant service that is rented on demand, becomes a capability that is yours — to you, your team or your organization.
| Dimension | AI in the cloud for tokens | Your private AI with Xeretron |
|---|---|---|
| Data path | Every request travels outside your control | Processing in your own environment |
| Cost structure | Variable cost per consumption | Installed capacity, more predictable cost |
| Models | Supplier dependency | Model selection and control |
| Information governance | Data subject to external policies | Local information governance |
| Connectivity | Internet as a central requirement | Works on your computer or server, even without internet |
Xeretron does not intend to eliminate the public cloud. It allows you to decide which loads should remain private in your environment and where it makes sense to combine both worlds by consuming giant models with external inference providers.
What is Xeretron
It's not a chat with another logo: it's a system that brings together models, hardware, security and services in one place — from a person's computer to a company's server.
Text and vision GGUF with upload, download and profiles managed from the node itself.
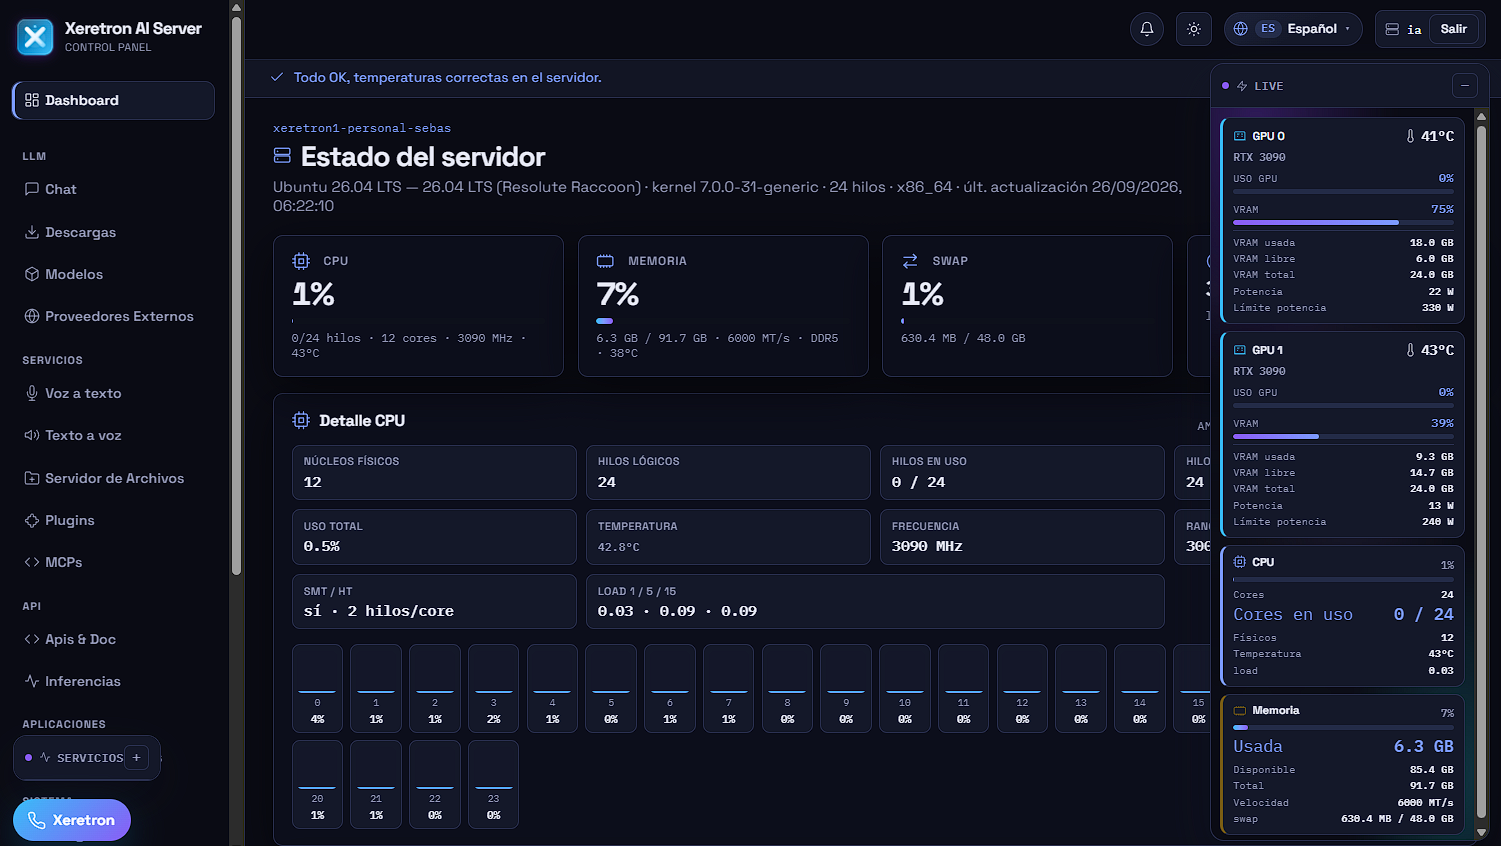
GPU, CPU, RAM, temperature and power in one clear HUD - you know what's happening in real time.
Chat, images, speech to text, documents and audio generated in the same local ecosystem.
Endpoints compatible with the OpenAI format plus own services to integrate your applications.
Authentication, MFA, API keys with limited scope and auditing of accesses and inferences.
Multi-GPU, network, firewall, services and power managed from the same interface.
The product, inside
What model is loaded, where it runs, how much it consumes and if the services are healthy. Each dashboard screen exists so that any person or team can operate their own AI without being engineering experts.
Capabilities
A set of specialized engines that share the same panel, the same security policy and the same infrastructure.
Text and vision with streaming, profiles, upload/download, lanes, stacks, frontier mode and metrics.
Local transcription with Whisper and idle flushing to free up GPU when not in use.
PDF, Office, images and spreadsheets converted to text in Spanish and English.
On-demand audio generation within the node, without sending the content to external services.
APIs, MCP/Unreal, SIP telephony, Sync and explicit hybrid.
System and application users, PAM, MFA, scoped keys, auditing and network.
Multi-GPU, firewall, services and energy consumption managed from the panel.
Interface and documentation in Spanish, English and Portuguese, ready for diverse teams.
Solutions
From your own team to an entire organization: each context has its own language and its own limits. Xeretron adapts to everyone.
An AI that strengthens the institution, not extracts its knowledge: academic assistants, regulation consultations, class transcription, accessibility and teaching support.
See casesExperiment with your own Xeretron models and quantizations, build applications with no variable cost per test, take care of datasets on campus and train talent in real infrastructure.
See casesAI close to the teams that care for people, with administrative and documentary cases. It does not replace medical judgment nor is it, by itself, a medical device.
See casesThe AI capacity of a public institution can also be public assets. Sovereignty does not mean isolation, and we do not claim automatic legal compliance.
See casesYour private AI on your own computer: an assistant for writing, studying and creating, with your data under your control. Ideal to start with the Personal plan.
See casesInternal assistants, document processing, automation, voice and operational continuity in the event of supplier or price changes. From a small team to the entire organization.
See casesMaximum flexibility of models and profiles to prototype products with your own AI, without each experiment being charged per token.
See casesPrivacy
Confidentiality does not depend on a declaration of intent: it depends on where the bytes travel, who can enter and what is recorded. Xeretron is designed around those controls.
We do not promise “inviolable” systems. We describe specific controls and the current limits of each deployment, which are defined in the pre-assessment.
Security and technologySecond factor access and session management from the node itself.
Each integration receives permission-limited and consumption-limited keys.
Security and inference logs to reconstruct what happened.
Controlled external exposure, encryption in transit and managed ports.
Economy
In the cloud, the cost grows linearly with your usage — and it doesn't stop. With Xeretron in your own environment, the conversation changes: a clear investment and a predictable annual cost, for a few users or for dozens.
How it works
We don't deliver an installer and we disappear. Every deployment starts with an assessment and ends with you — or your team — operating your AI autonomously.
What data will be processed, what models you need, how many users, what hardware exists and what availability you expect.
Preparation of the node, CUDA and services, initial catalog of models and HTTPS over your network.
Users, roles, API keys, connections with your applications and training of the responsible team.
Boot support, performance adjustments, agreed updates and results reporting.
First inference in days, not months
Plans
From personal equipment to organization: all plans include installation, training and start-up support. Additional user on any plan: $29 USD / year.
For you and up to 3 users
Regular price: $1,299 USD
+ $299 / year · license maintenance and updates
Small teams · up to 10 users
+ $799 / year · license maintenance and updates
Schools · NGOs · up to 20 users
+ $999 / year · license maintenance and updates
Organizations · up to 50 users
+ $1,399 / year · license maintenance and updates
Prices in USD, per installation. Each additional user over the plan limit is added to $29 USD/year. Additional GPU license $99/year. Final amounts are confirmed after evaluation of your case.
Voices of the program
Developers, operational teams and business owners who already run their models on their own infrastructure.
I used to pay for tokens every time the model got stuck in a large refactor. Now I run everything local with Xeretron: I iterate without fear, I try three approaches at once and the monthly cost is the same as the first month. For vibe coding, the freedom of unlimited use completely changes the flow.
We built a document agent that reads contracts, extracts key clauses and puts together summaries in minutes. Previously, it took two analysts an afternoon to review a file. With our own node, sensitive documents never leave our networks and the volume of paperwork grew without hiring more people.
I use XMail to respond to routine emails and check my schedule without touching my phone in the morning. The node responds with my tone, prioritizes what is urgent and makes my day. I regained hours every week and, above all, my business conversations do not go through a third-party cloud.
We migrate technical product documentation to the node: engineers consult manuals, sheets and protocols with answers in seconds. Before, half a day was lost searching for the correct information. Today each team responds alone and knowledge of the area no longer depends on a single person.
As a graduate student I need to experiment without each test costing me a subscription. With my own node I test and compare models 24 hours a day, and everything remains on my server: my academic data does not go to an external provider nor does it appear in some other log.
As a small law firm we could not afford an analyst to review each contract. Today our document agent reads, classifies and resolves files at night, and in the morning the team only reviews what is important. The investment paid for itself in two months, and nothing we signed leaves our network.
Each case operates on its own infrastructure with Xeretron models. Results vary depending on plan, hardware, and volume of usage.
Allies Program
Accompanied deployment, close access to the team and direct participation in the evolution of the product. At this stage it is not self-service: it is your private AI, installed and accompanied.
History
Xeretron is born from a simple conviction: The world should not limit itself to consuming artificial intelligence governed from other places. It is not a story of founders; It's the quiet work of making a node work, every day, under real-world conditions.
Meet XeretronThe question is no longer “do we use AI?” Is:
Frequently asked questions
Local components work if the models are already installed. Model downloads and external integrations may require connectivity. We define what remains offline in the evaluation of your architecture.
Yes, Xeretron has its own models from 4B to 552B and they are available according to your plan or you can purchase them separately, you can also manage and operate the models within the node. The specific selection of models and their licenses depends on your use case and is defined in the project.
Not necessarily. It can operate in private or hybrid mode: you decide which loads remain inside and where it is convenient to combine both worlds.
It depends on the models and the expected attendance. That is why prior evaluation is mandatory: we size GPU, RAM and disk before proposing a configuration.
Local flows can stay entirely within your network. Any exit to an external service occurs only if you explicitly enable it.
No. It is infrastructure plus human supervision: it amplifies capacity, it does not replace the professional judgment of those who teach, research, care or serve.
We use the best open weight models and fine tune them so that they work correctly with our entire ecosystem.
With deployments accompanied in this initial stage: diagnosis, installation, configuration, training and start-up support.
Yes, through API compatible with the OpenAI format and own services, with access keys limited by scope, according to the project agreement.
Next step